
Install Anaconda, PySpark, and Jupyter Notebook
If you are not using Anaconda, you can skip this lesson. This lesson is required only if you wanted to run PySpark in Anaconda platform.
How to install PySpark in Anaconda & Jupyter Notebook on Windows or Mac? In this lesson, I will explain the step-by-step installation of PySpark in Anaconda and run examples in Jupyter Notebook. In case you are not aware, Anaconda is the most used distribution platform for Python & R programming languages in the data science & machine learning community as it simplifies the installation of packages like PySpark, pandas, NumPy, SciPy, and many more.
Note: Please use the latest version. The Java, Scala, and Spark versions I used in this lesson might be older depending on when you are using it. I would highly recommend using the latest available versions for each tool.
Steps to Install PySpark in Anaconda & Jupyter Notebook
- Step 1. Download & Install Anaconda Distribution
- Step 2. Install Java
- Step 3. Install PySpark
- Step 4. Install FindSpark
- Step 5. Validate PySpark Installation from pyspark shell
- Step 6. PySpark in Jupyter notebook
- Step 7. Run PySpark from IDE
Download & Install Anaconda Distribution
Go to https://anaconda.com/,and download the Anaconda, and install. For Windows you download the .exe file and for Mac download the .pkg file.

After finishing the installation of the Anaconda distribution, install Java and PySpark. Note that to run PySpark you would need Python which is installed with Anaconda.
Install Java
PySpark uses Java underlying hence you need to have Java on your Windows or Mac. Since Java is a third-party, you can install it using the Homebrew command brew. Since Oracle Java is not open source anymore, I am using OpenJDK version 11. Open Terminal from Mac or command prompt from Windows and run the below command to install Java.
# Install OpenJDK 11conda install openjdk
The following Java version will be downloaded and installed. Note that I am using a Mac. Depending on the OS and version you are using the installation directory would be different.

Install PySpark
To install PySpark on Anaconda I will use the conda command. conda is the package manager that the Anaconda distribution is built upon. It is a package manager that is both cross-platform and language-agnostic.
# Install PySpark using Condaconda install pyspark
The following packages will be downloaded and installed on your Anaconda environment. Note that based on your PySpark version you may see fewer or more packages.

Install FindSpark
In order to run PySpark in Jupyter Notebook first, you need to find the PySpark Install, I will be using findspark package to do so. Since this is a third-party package we need to install it before using it.
conda install -c conda-forge findspark
Validate PySpark Installation
Now let's validate the PySpark installation by running pyspark shell. This launches the PySpark shell where you can write PySpark programs interactively.
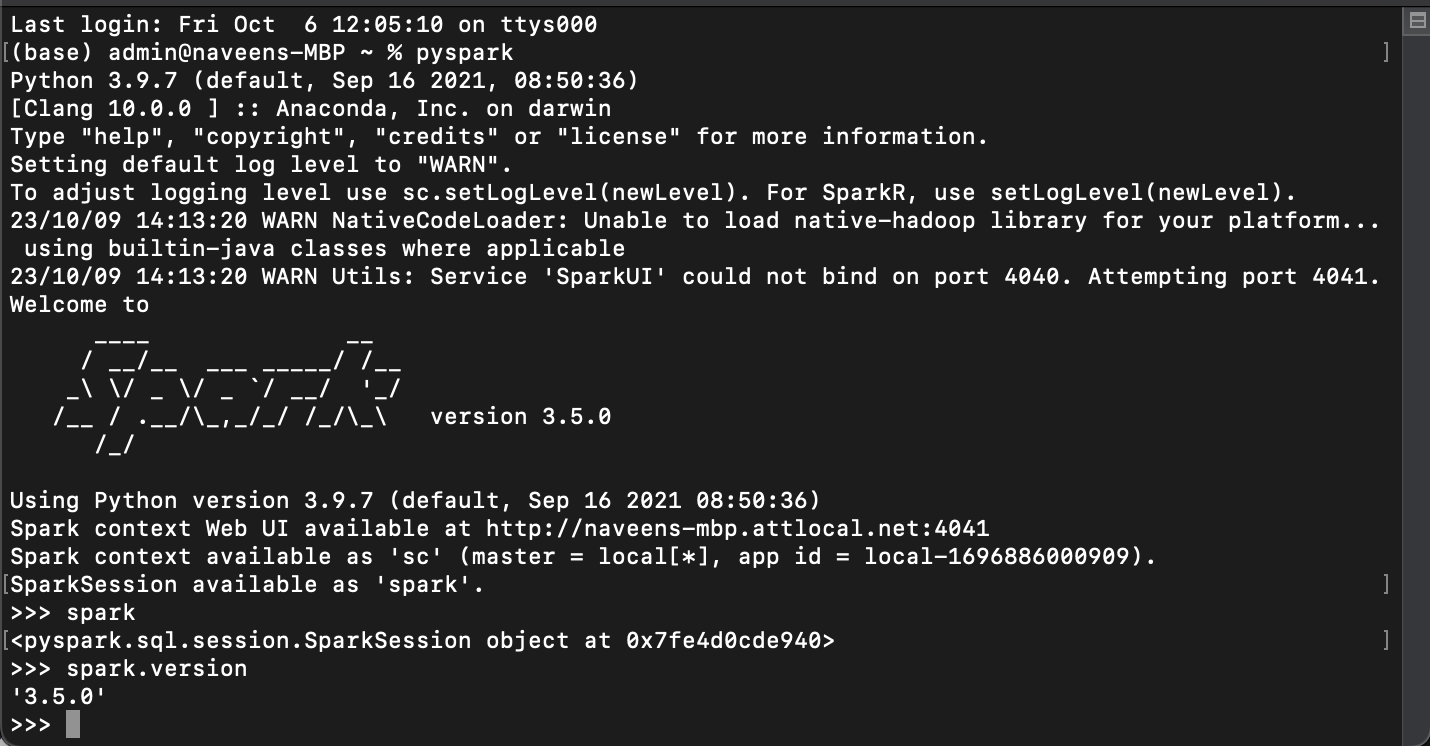
Let's create a PySpark DataFrame with some sample data to validate the installation. Enter the following commands in the PySpark shell in the same order. Note that SparkSession 'spark' and SparkContext 'sc' is by default available in PySpark shell.
# Create DataFrame in PySpark Shelldata = [("Java", "20000"), ("Python", "100000"), ("Scala", "3000")]df = spark.createDataFrame(data)df.show()
Yields below output. For more examples on PySpark refer to PySpark Tutorial with Examples.

Now access http://localhost:4041/jobs/ from your favorite web browser to access Spark Web UI to monitor your jobs.
Install Jupyter Notebook & run PySpark
With the last step, the PySpark install is completed in Anaconda and successfully validated the installation by launching the PySpark shell and running the sample program now, let's see how to run a similar PySpark example in Jupyter Notebook.
Now open Anaconda Navigator - For windows use the start or by typing Anaconda in search. and for Mac, you can find it from Finder => Applications or from Launchpad. Anaconda Navigator is a UI application where you can control the Anaconda packages, environment etc. If you don't have Jupyter Notebook installed on Anaconda, just install it by selecting Install option.
Post-install, Open Jupyter by selecting Launch button.

This opens up Jupyter Notebook in the default browser.

Now select New -> PythonX and enter the below lines and select Run. On Jupyter, each cell is a statement, so you can run each cell independently when there are no dependencies on previous cells.
If you get pyspark error in jupyter then then run the following commands in the notebook cell to find the PySpark .
import findsparkfindspark.init()findspark.find()
Run the below commands to make sure the PySpark is working in Jupyter. You might get a warning for the second command "WARN util.NativeCodeLoader: Unable to load native-hadoop library for your platform” warning, ignore that for now.

Run PySpark from Spyder IDE
If you don't have Spyder on Anaconda, just install it by selecting Install option from the Anaconda navigator.
post-install, Open the Spyder to write the below program, and run it by pressing F5 or by selecting a run button from the menu.
# Import PySparkfrom pyspark.sql import SparkSession#Create SparkSessionspark = SparkSession.builder.appName('AIStudyLabs.com').getOrCreate()# Datadata = [("Java", "20000"), ("Python", "100000"), ("Scala", "3000")]# Columnscolumns = ["language","users_count"]# Create DataFramedf = spark.createDataFrame(data).toDF(*columns)# Print DataFramedf.show()

This completes the PySpark install in Anaconda, validating PySpark, and running in Jupyter Notebook & Spyder IDE. I have tried my best to layout step-by-step instructions, In case I miss any or you have any issues installing, please let me know. Your comments might help others.