
Introduction
There are multiple ways to install PySpark on Mac, I have explained the step-by-step of PySpark installation on Mac OS using Homebrew, running PySpark shell, and creating a PySpark DataFrame. Besides this, you can also install PySpark using Anaconda and run a program from Jupyter Notebook.
Note: Please use the latest version. The Java, Scala, and Spark versions I used in this lesson might be older depending on when you are using it. I would highly recommend using the latest available versions for each tool.
Steps to install PySpark on Mac OS using Homebrew
- Step 1 - Install Homebrew
- Step 2 - Install Java
- Step 3 - Install Scala (Optional)
- Step 4 - Install Python
- Step 5 - Install PySpark
- Step 6 - Start PySpark shell and Validate Installation
Install PySpark on Mac using Homebrew
Homebrew is a Missing Package Manager for macOS (or Linux) that is used to install third-party packages like Java, PySpark on Mac OS. In order to use this, first, you need to install it by using the below command.
# Install Homebrew
/bin/bash -c "$(curl -fsSL https://raw.githubusercontent.com/Homebrew/install/HEAD/install.sh)"
This prompts for the root password. You will need to type your root password to run this command. On a personal laptop, this is the same password you enter when you log into your Mac. If you don't have root access, contact your system admin.
Post-installation, you may need to run the below command to set the brew to your $PATH.
# Set brew to Path
echo 'eval "$(/opt/homebrew/bin/brew shellenv)"' >> /Users/admin/.zprofile
eval "$(/opt/homebrew/bin/brew shellenv)"
If the above command has issues, you can find the latest command from Homebrew.
Install Java Version
PySpark uses Java underlying hence you need to have Java on your Mac. Since Java is a third-party, you can install it using the Homebrew command brew. Since Oracle Java is not open source anymore, I am using OpenJDK version 21. Run the below command in the terminal to install it.
# Install OpenJDK 21
brew install openjdk@21
Install Scala
Since Spark is written in Scala language it is obvious you would need Scala to run Spark programs, however, to run PySpark this is optional.
# Install Scala (optional)
brew install scala
Install Python
As you would know, PySpark is used to run Spark jobs in Python hence you also need Python to install on Mac OS. let's install it by using Homebrew. If you already have Python 2.8 or the latest then ignore this step.
# Install Python
brew install python
Install PySpark
PySpark is a Spark library written in Python to run Python applications using Apache Spark capabilities. Spark was basically written in Scala and later on due to its industry adaptation its API PySpark was released for Python using Py4J. Py4J is a Java library that is integrated within PySpark and allows Python to dynamically interface with JVM objects, hence to run PySpark you also need Java to be installed along with Python, and Apache Spark. So to use PySpark, let's install PySpark on Mac.
# Install Apache Spark
brew install apache-spark
This installs the latest version of Apache Spark which ideally includes PySpark. For me it installed Spark version 4.1.1.
Alternatively, download Apache Spark by accessing the Spark Download page and select the link from “Download Spark (point 3 from below screenshot)”.
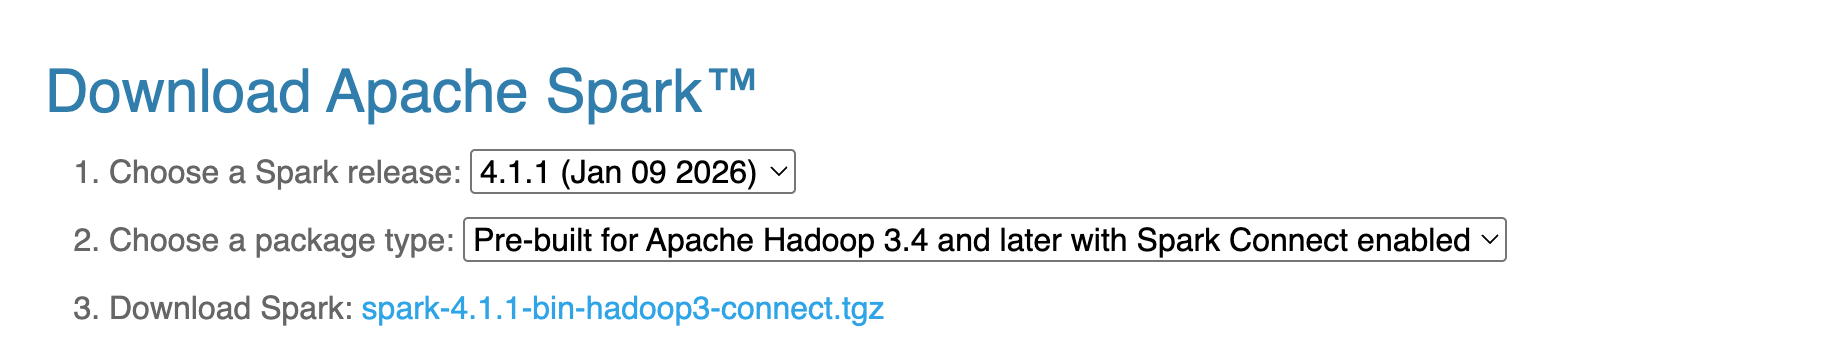
If you want to use a different version of Spark & Hadoop, select the one you wanted from the drop-down; the link on point 3 changes to the selected version and provides you with an updated link to download.
After download, untar the binary using 7zip or any zip utility to extract the zip file and copy the extracted directory spark-4.1.1-bin-hadoop3-connect to ~\apps\opt\spark-4.1.1-bin-hadoop3-connect. Make sure you set the ~\apps\opt\spark-4.1.1-bin-hadoop3-connect\bin to the PATH environment variable in the profile file and reload the terminal.
After the successful installation of Apache Spark run pyspark from the command line to launch PySpark shell.
<img height="302" width="678" src="https://yrltjyzsmzdylqvoonwf.supabase.co/storage/v1/object/public/lesson-images/100/183/pyspark-shell-v4.png" />
Note that it displays Spark and Python versions to the terminal.
Now access http://localhost:4041/jobs/ from your favorite web browser to access Spark Web UI to monitor your jobs.
Note: Spark by default creates Spark context web UI with port 4040, if this port is already taken then it uses 4041. In my case, it is listening on 4041.
<img height="263" width="742" src="https://yrltjyzsmzdylqvoonwf.supabase.co/storage/v1/object/public/lesson-images/100/181/spark-web-ui-v4.png" />
Summary and Key Takeaways
By following the steps outlined in this lesson, you have successfully set up a PySpark environment on your Mac using Homebrew. PySpark's capabilities allow you to harness the power of Apache Spark for data processing with Python, making it a valuable tool for data scientists and engineers.
- Use Homebrew to simplify the installation of essential software components like Java, Python, and Apache Spark on Mac OS.
- Ensure Java and Python are installed as they are prerequisites for running PySpark efficiently.
- You can monitor your Spark jobs through the Spark Web UI accessible at the specified port.